Flaremender
Open-source agent that explores your app in a real browser, writes and repairs Playwright tests, and runs them on a schedule. Self-hosted on your own Cloudflare account with a one-click deploy.
About
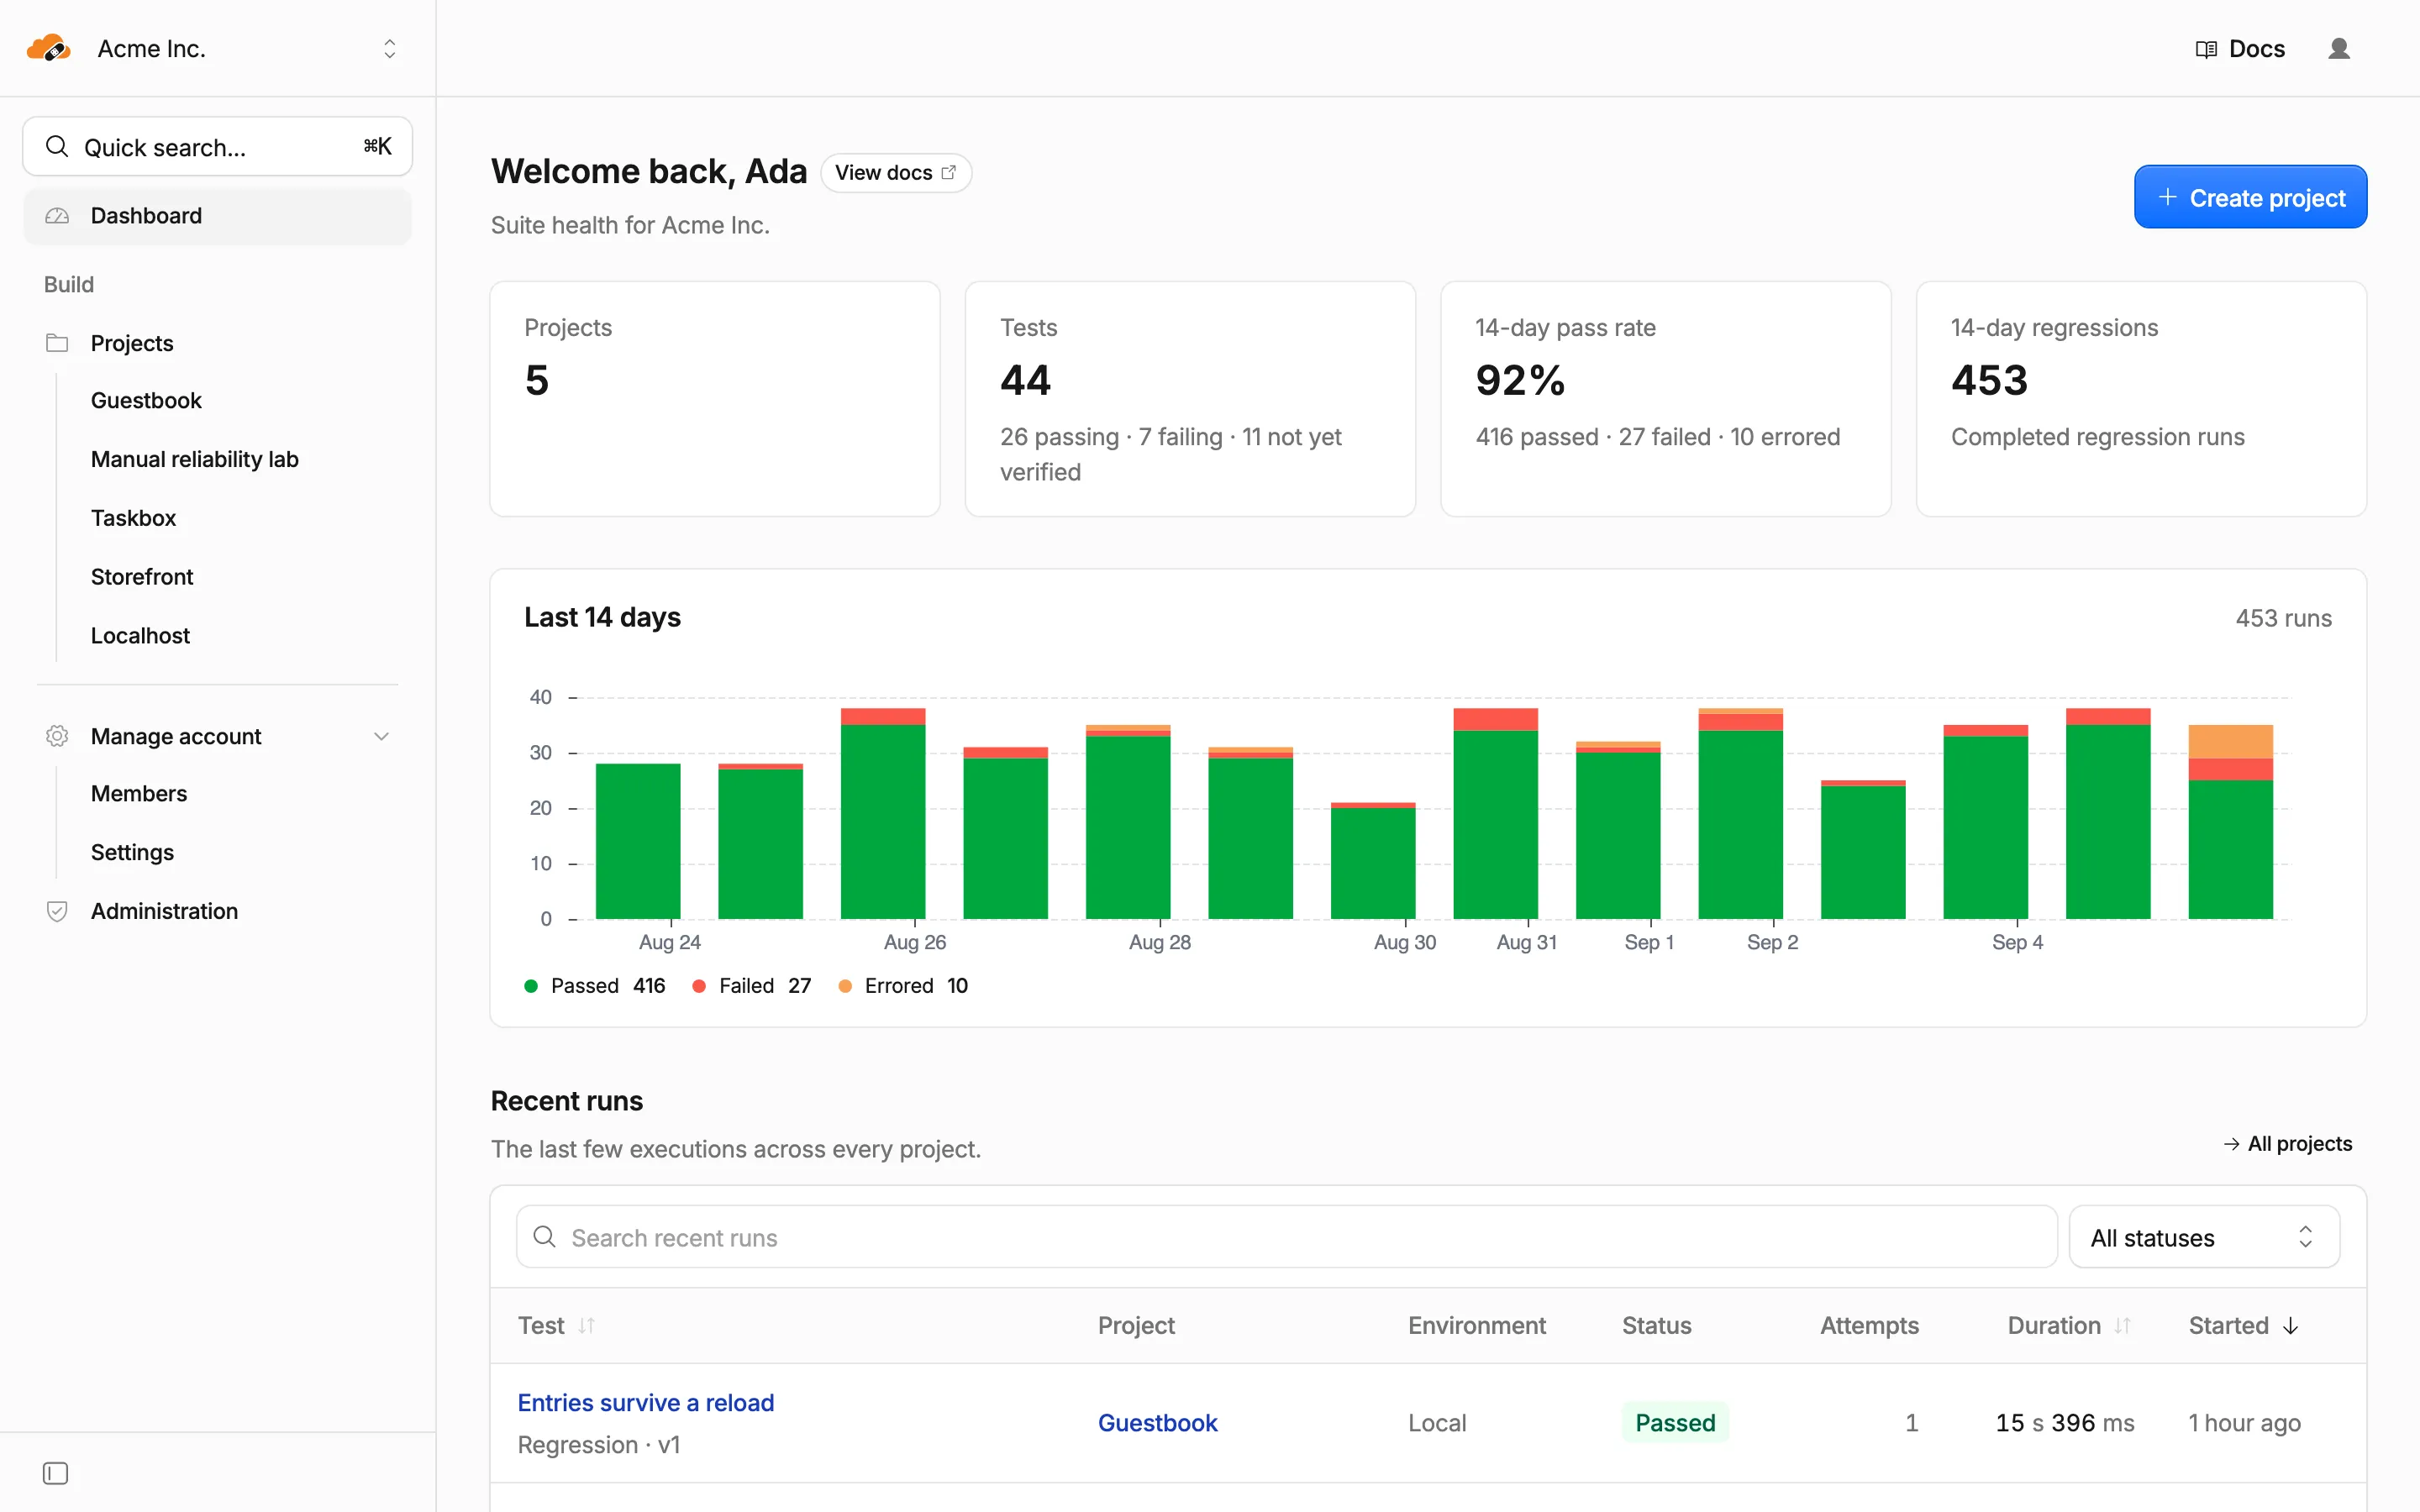
Flaremender is an end-to-end test runner with an agent in it. Point it at your app and give it a sign-in. The agent opens the app in a real browser, works out what it does, proposes the tests worth having and writes them. Every test is verified in a fresh browser before it is kept. What comes back is ordinary Playwright you can read, edit or take elsewhere.
It runs entirely on your own Cloudflare account. Your app’s credentials, your scripts and your run history never leave it.
Why I built it
End-to-end suites are expensive to write and they rot fast. The AI tools that fix this usually want your app’s credentials and test history on their servers. I wanted the same convenience without handing any of that over, and I wanted to see how far the Cloudflare developer platform could carry a whole product with no other infrastructure. The answer was all the way.
What I built
- An exploration agent that browses an app, reads any docs it is given, and proposes a first suite
- A generation loop that performs a flow in a live browser and keeps only the steps it has watched work
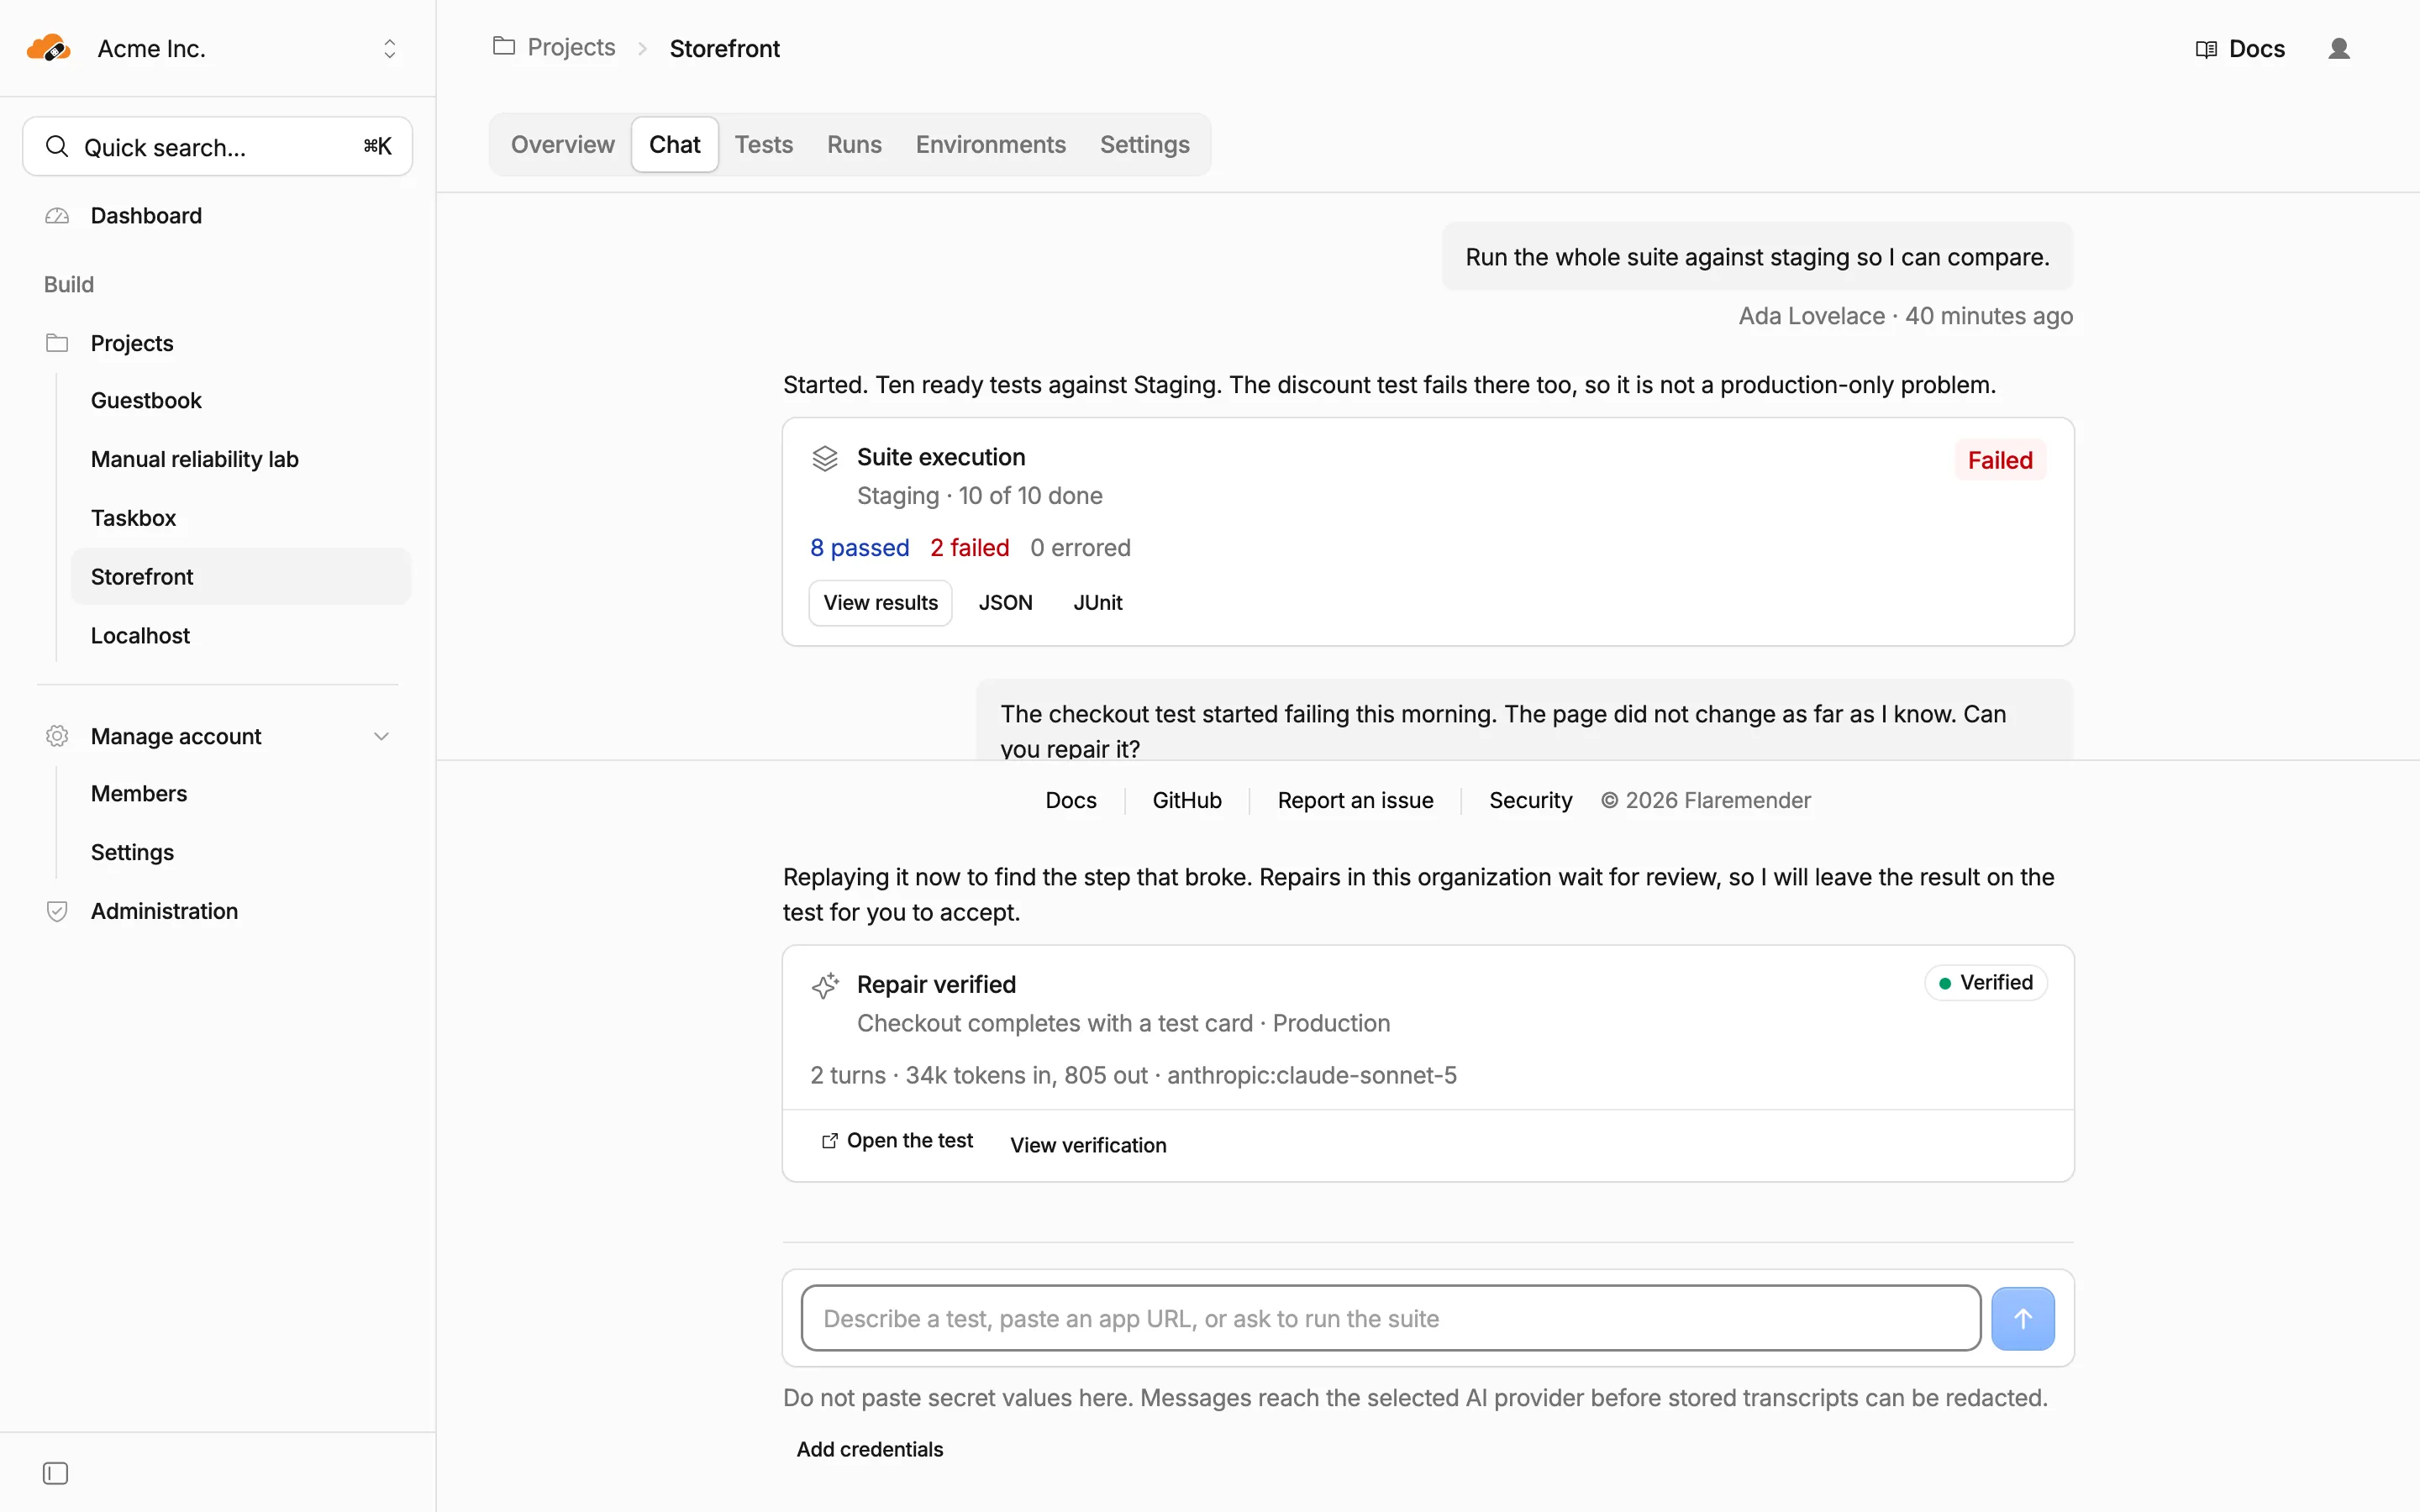
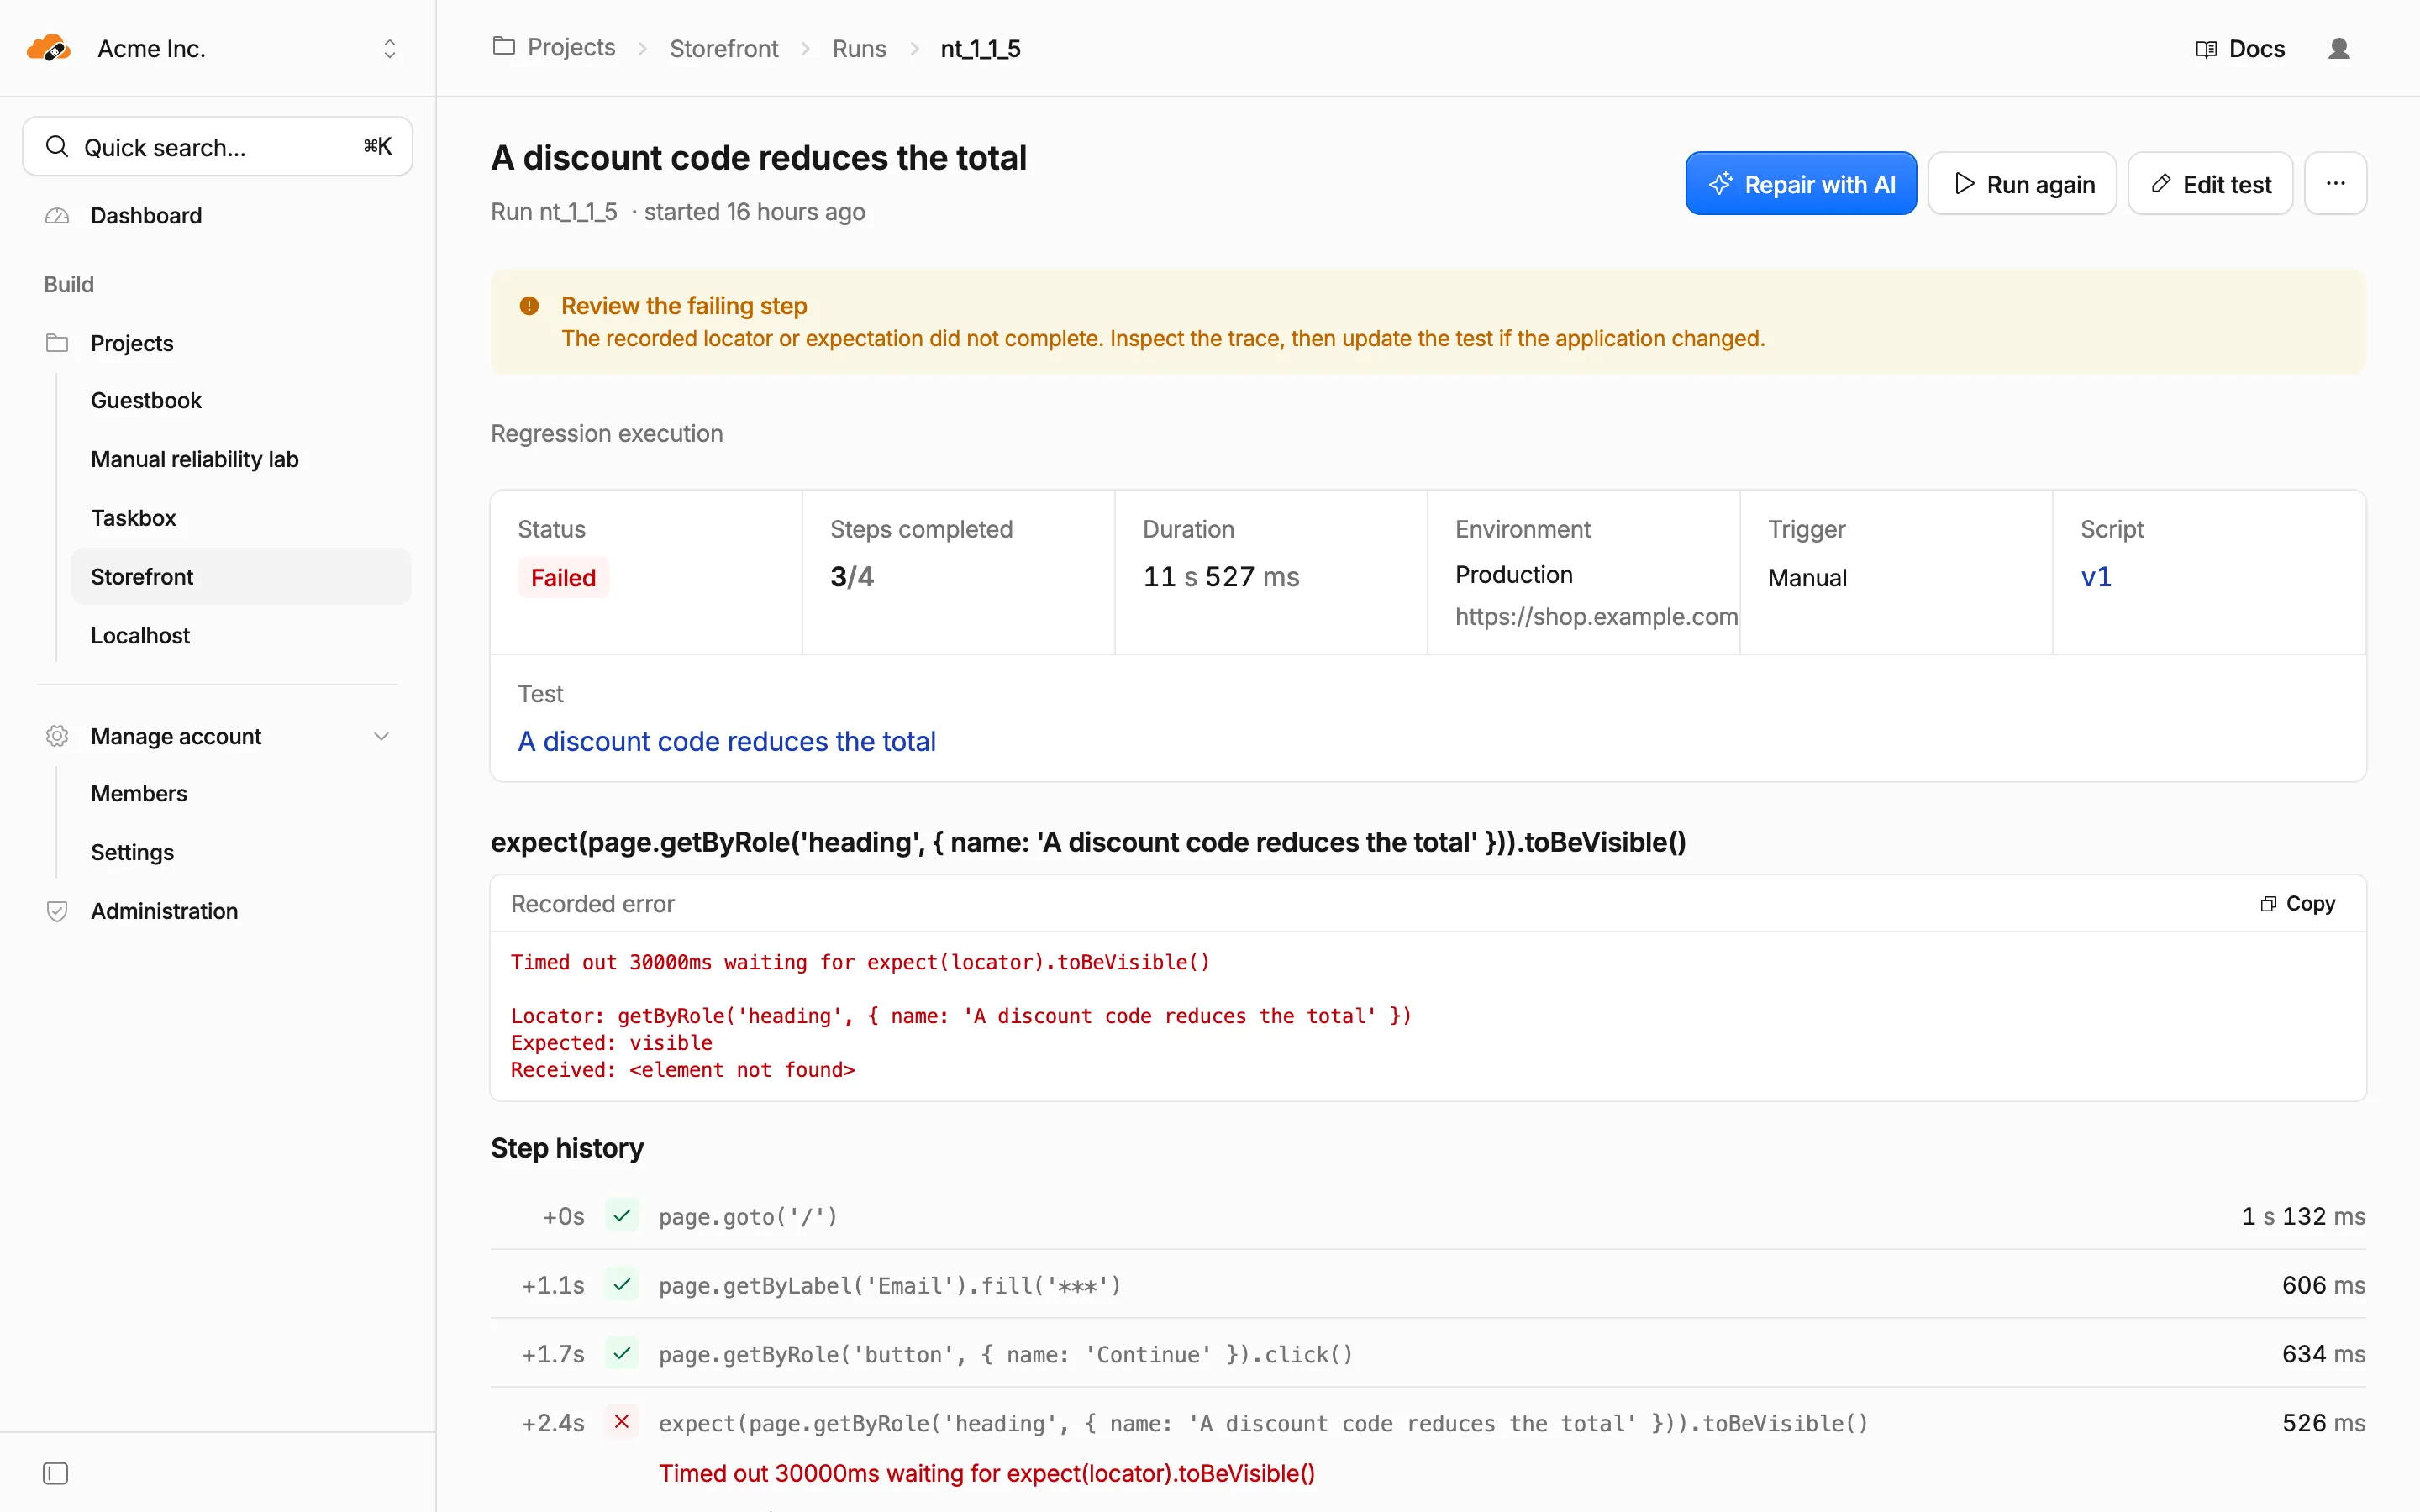
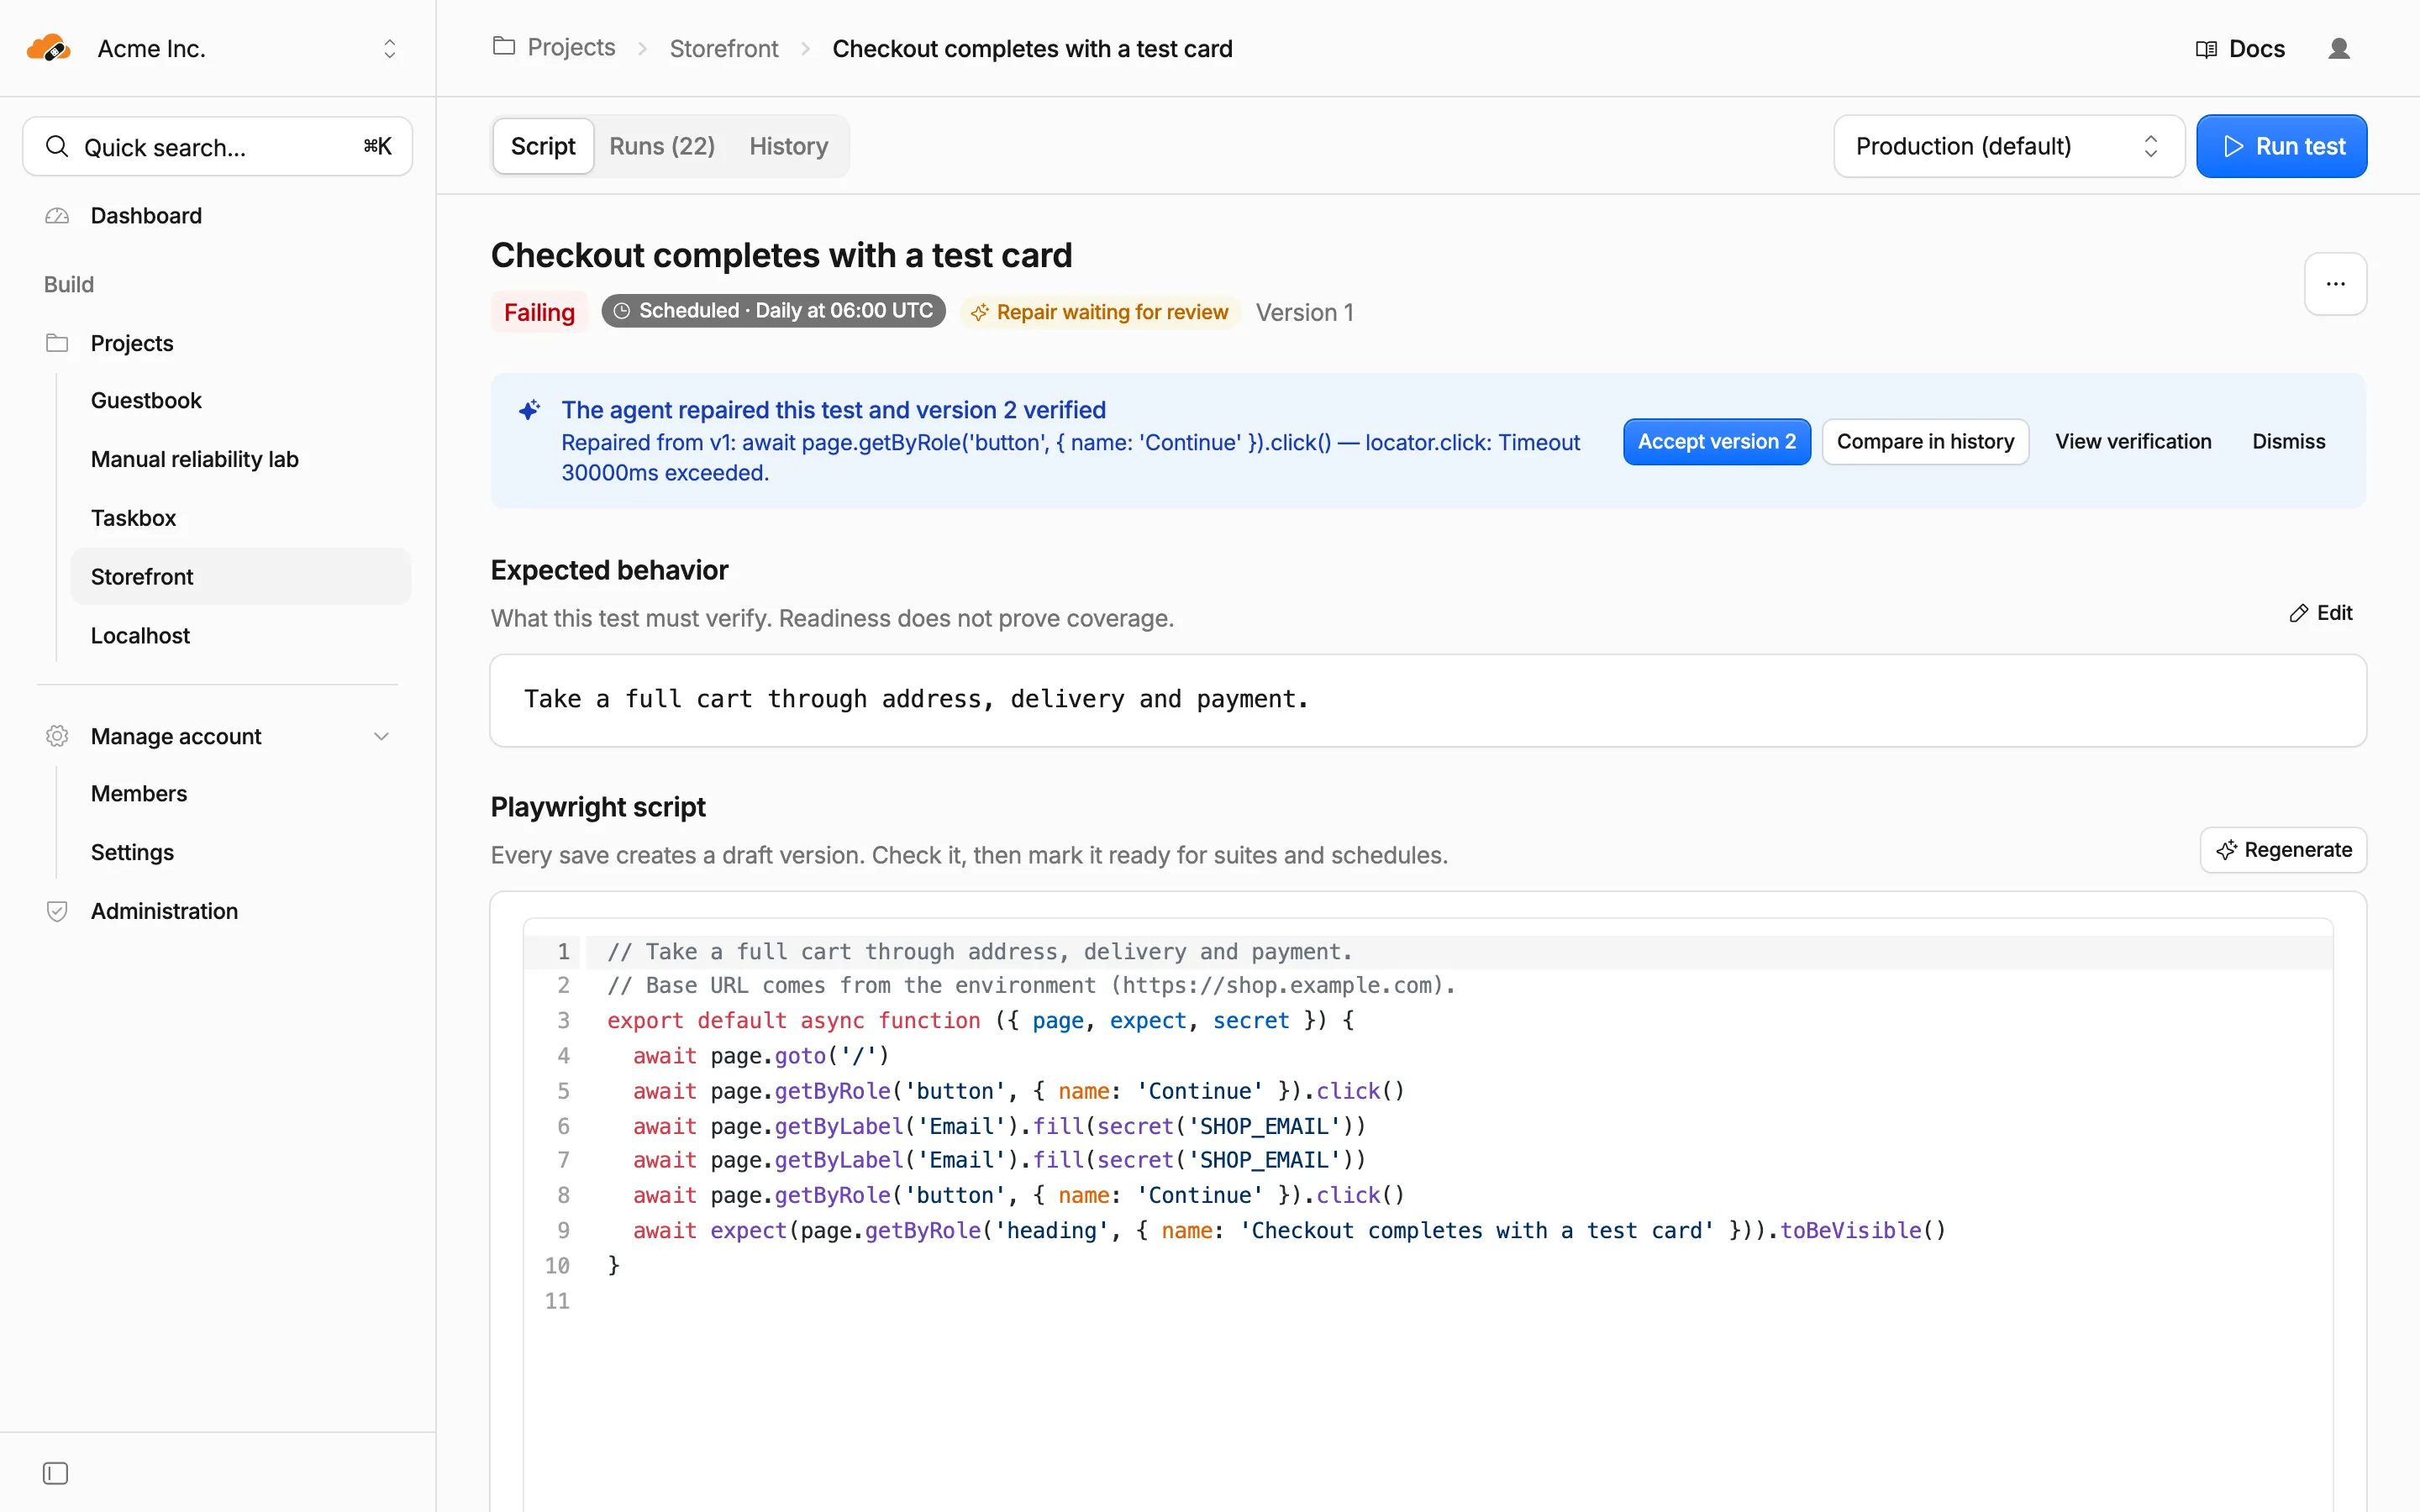
- A repair loop that replays a failing script to the broken step, replaces that step and verifies the result
- Scheduled and CI-triggered runs with a webhook API, idempotency keys and JUnit output
- Notifications to signed webhooks, Slack, Discord and email
- An MCP server, so Claude, Cursor or Claude Code can ask for tests, runs and repairs over OAuth
- An eval harness that scores generation across models against fixed example apps
Engineering decisions
These are the parts I would defend.
- Every generated script runs in its own sandbox. Scripts execute in a Dynamic Worker with only a browser binding. A bad or hostile test cannot reach the database, object storage or the network.
- Readiness is separate from outcome. The agent never marks a test ready on its own judgment. Only a full replay passing in a fresh browser does. Anything less stays a draft for a person.
- Redact before you truncate. Secrets are replaced with
***in logs, labels and errors before anything is stored, and the scrubber runs before any string is clipped, because clipping first defeats it. - A proposed test is not a test. Proposals sit in their own status and are excluded from suites, schedules and every count until someone approves them.
- Repairs are bounded and off by default. One automatic attempt per script version, replacing only the failing step, and a policy per organization, project or test decides whether a repair waits for review or is adopted.
Stack
TanStack Start on Cloudflare Workers, Workflows for the long-running jobs, Durable Objects for the live browser feed and project chat, D1 through Drizzle, R2 for artifacts, Browser Rendering, Dynamic Workers for the sandbox, AI Gateway for model routing, and Cloudflare’s Kumo design system for the UI.